

 Create Account
Last updated: October 2026
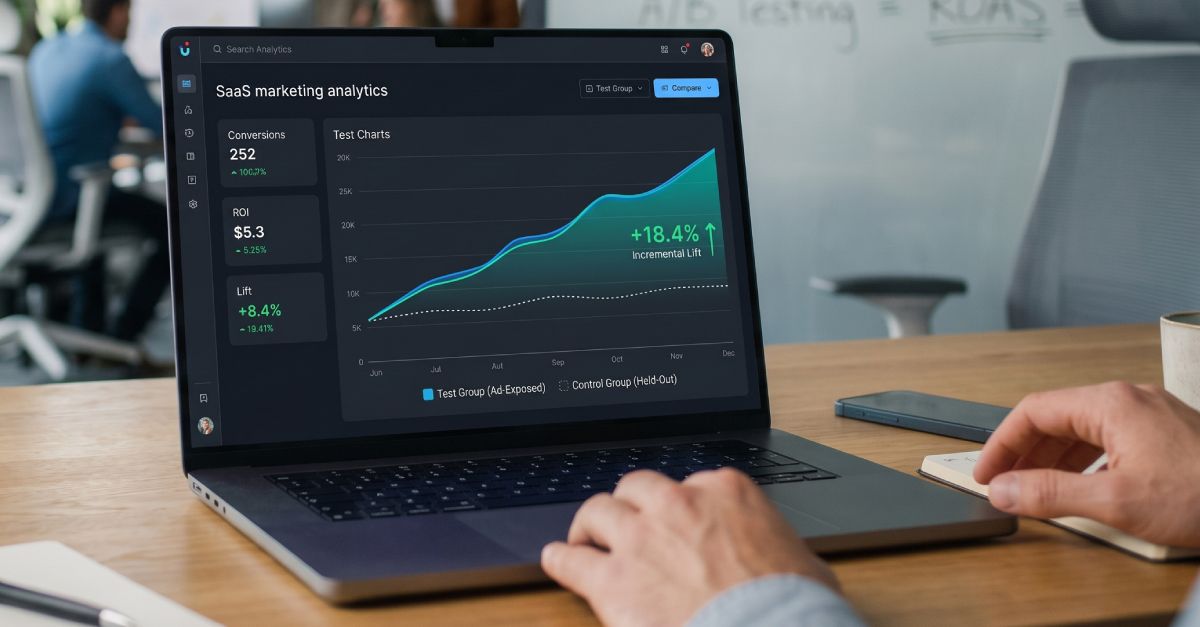
Incrementality testing measures how many conversions your advertising caused by comparing people who could see your ads with a similar group who were held back from them. The difference between the two groups, called incremental lift, is what the campaign added on top of the sales that would have happened anyway.
It works best alongside attribution, not instead of it. Attribution is the running record of what every channel did. An incrementality test is a controlled snapshot of one of them. Attribution follows each buyer’s path from first impression to conversion and shows, every day, which channels, creative, and audiences are moving people toward a sale. A lift test steps back a few times a year and measures how much a single channel or campaign added in total. For nationwide and ecommerce brands with steady sales volume, both belong in the plan.
Key Takeaways
- Incrementality testing measures how much a campaign added by comparing an exposed group with a held-out control group. Attribution shows how every channel contributed along the way, every day.
- The two work together. Attribution steers daily decisions, and a lift test checks one channel’s total effect a few times a year.
- Nationwide and ecommerce brands with steady sales volume get the most from testing. Use platform lift tests for one platform and geo-lift tests for CTV, audio, DOOH, and offline sales.
- Pick the success metric before launch, run for at least two weeks and a full buying cycle, don’t stop early, and read the result as a range.
What Is Incrementality Testing?
Incrementality testing is a controlled experiment that estimates the counterfactual: what would have happened if the campaign had never run. You can’t watch the same person both see and not see an ad, so you build two groups that are alike in every way except exposure and compare them.
It has become a standard part of the measurement mix. The IAB’s 2026 State of Data report found that among US buy-side decision-makers, 76% use incrementality tests, 73% use attribution, and 67% use media mix modeling, and it says testing’s popularity is driven by how easy platforms have made built-in holdout tests (IAB, 2026). Proving performance has become a priority, too. In a 2025 TransUnion and EMARKETER survey of 196 US marketers, 67% said they now prioritize incremental ROI, and 55% said the same about improving cross-channel attribution (TransUnion, 2025).
Six terms come up in every test:
- Test group. The audience, households, or regions eligible to see the campaign.
- Control group (holdout). A comparable audience deliberately kept from seeing it. In Meta’s lift tests, it’s the part of your target audience that is held back from your ads on purpose (Meta).
- Incremental lift. The difference in results between the two groups, usually shown as a percentage of the control group’s result.
- Incremental conversions. The extra conversions the campaign caused, beyond what the control group’s rate predicts.
- iROAS. Incremental revenue divided by ad spend. It’s the return measured against a group that never saw the ads.
- Incrementality factor. Incremental sales divided by the sales a platform reported (Haus, 2025). It’s a calibration you can apply to a channel’s reporting between tests.
A Simple Incrementality Example
Say a campaign targets 200,000 people and randomly holds back 20,000 of them. Over four weeks, the exposed group converts at 2.4% and the holdout converts at 2.0%. The lift is (2.4 - 2.0) / 2.0, or 20%. Across 180,000 exposed people, that 0.4-point gap works out to 720 incremental conversions. If the average order is worth $150 and the campaign cost $40,000, the incremental revenue is $108,000 and the iROAS is 2.7.
That’s a number you can take to a finance team, because it was measured against a group that never saw the ads.
What’s the Difference Between Incrementality and Attribution?
Attribution tracks the impressions and touchpoints on each buyer’s path to conversion and shows how every channel contributed, continuously. Incrementality testing withholds ads from a control group for a set period to measure how much one channel or campaign added in total. Attribution runs every day. A lift test is a periodic check.
| Attribution | Incrementality Testing | |
|---|---|---|
| Question it answers | Which channels, creative, and audiences moved buyers toward each conversion? | How many more conversions did this campaign cause than no campaign at all? |
| How often | Every day, on every campaign | A few times a year, one question at a time |
| Level of detail | Impression, creative, audience, channel, and full path | One channel, campaign, or set of regions |
| What it costs | Part of running the campaign | Reach withheld from the holdout during the test |
| Best for | Daily optimization and moving budget between channels | Confirming the size of a channel’s effect before a big budget decision |
Neither replaces the other. A lift test can confirm that a CTV campaign added sales in the regions where it ran. It can’t tell you which creative, which audience, or which path from first impression to purchase did the work. A lift test tells you how much a channel added. Attribution tells you how and where. That’s the information you need to act on a test result.
When Do Lift Tests and Attribution Disagree?
When a lift test and attribution disagree, look first at what that attribution setup can see. Most platforms grade their own homework, with last-click credit, modeled impressions, and numbers you can’t audit. Two well-studied cases show how that plays out:
- Click-only reporting undercounts. In Haus’s analysis of 640 Meta experiments, every $100 of direct-to-consumer revenue that 7-day-click attribution credited to Meta matched $115 of incremental revenue (Haus, 2025).
- Last-click search overcounts. Brand search ads reach people who are already looking for you. Large field experiments at eBay found that brand keyword ads had no measurable short-term benefit (Blake, Nosko, and Tadelis, 2015). When eBay paused its brand search ads on Yahoo and MSN, 99.5% of the lost clicks came back through organic search (NBER working paper, 2014). Giving the last click all the credit rewarded the final step of a purchase that was already underway.
Both cases come down to what the model counted. Attribution that follows the full path, impressions as well as clicks and every channel rather than the last one touched, sees more of what each channel actually did. That matters for CTV, audio, and DOOH, which rarely earn a click, and it’s why impression tracking is the base of good measurement. A lift test is how you confirm it.
Who Should Run Incrementality Tests?
Nationwide and ecommerce brands with steady sales volume get the most from incrementality testing. They have the conversions to reach a clear result, enough markets to build matched test and control regions, and budgets large enough that a sharper read on one channel moves real money. For them, testing should be a routine part of the plan.
- Volume. Google’s Conversion Lift requires at least 1,000 observed conversions (Google). Brands that sell online, nationally, reach that faster.
- Markets. Meta’s GeoLift guidance calls for at least 25 pre-test periods across 20 or more regions (GeoLift Best Practices). A national footprint makes that easy to meet.
- Stakes. Every incrementality study comes with an opportunity cost, because the holdout doesn’t see your ads (Google). That cost is easiest to justify when the channel under test carries a large share of the budget.
Smaller and regional brands can still test, and it’s cheaper than it used to be. But they may not reach the volume or the number of markets a clean result needs. For them, strong attribution does most of the measurement work, and a test makes sense when one large budget decision is on the line.
How Does Incrementality Testing Work?
Incrementality testing works by splitting a comparable audience or set of markets into two groups, exposing only one of them to the campaign, and comparing results over the same period. Because the groups match on everything except ad exposure, the difference in outcomes can be credited to the ads.
Three conditions have to hold for the answer to mean anything:
- The groups have to be comparable. Random assignment is the gold standard. When you can’t randomize people, you match test and control regions on their past sales (GeoLift Best Practices).
- The test needs enough volume. Individual sales swing widely relative to what the ads cost per person. Across 25 large field experiments with major US retailers and brokerages, the median confidence interval on return on investment was more than 100 percentage points wide (Lewis and Rao, 2015). Small tests produce wide, inconclusive ranges.
- The test has to run long enough. It needs to cover at least one full purchase cycle (GeoLift Best Practices). More on that below.
Platforms set their own bars for a trustworthy result. For lift tests, Meta treats 90% or higher confidence as a statistically reliable result, and it typically suggests an estimated power of 80% or more before launch (Meta). Google’s Conversion Lift provides budget guidance aimed at 90% certainty of lift (Google).
What Are the Main Types of Incrementality Tests?
The main types of incrementality tests are user-level holdouts run inside an ad platform, geo-lift tests that compare regions, ghost-ad tests, PSA or placebo tests, and simple on/off tests. They differ in what they can measure, how precise they are, and what they cost.
| Test Type | How It Works | Best For | Watch Out For |
|---|---|---|---|
| User-level holdout (conversion lift) | The platform randomly withholds ads from a slice of your target audience and compares conversions | Single-platform campaigns on Google, Meta, and other walled gardens | Measures only that platform, using the platform’s own data |
| Geo-lift (matched market) | Ads run in some regions and are withheld in comparable regions | Cross-channel, CTV, audio, DOOH, and offline sales | Needs enough regions and clean history, and local events can skew results |
| Ghost ads | The ad system logs when it would have shown your ad to a control user, without showing it | Precise user-level lift without paying for placeholder ads | Requires a platform that supports it |
| PSA (placebo) test | The control group sees an unrelated public service ad instead of yours | Simple setups where ghost ads aren’t available | You pay for the placebo impressions |
| On/off (time-based) test | A channel is paused for a period and compared with periods when it ran | Rough reads when no other design is possible | Seasonality and other changes muddy the comparison |
Platform lift tests are the most common. Among US buy-side teams that test regularly, 54% run platform lift studies, 45% run geo-based lift tests, and 38% run cross-channel tests (IAB, 2026). They also got much cheaper. Google cut the minimum budget for its incrementality tests from what could run upwards of $100,000 to $5,000 in November 2025, and says its updated methodology returns conclusive results up to 50% more often (Google, 2025).
Geo-lift tests answer questions platform tests can’t, such as whether CTV, audio, or DOOH moved total sales, online and offline. Meta’s open-source GeoLift package, built on synthetic control methods, is one free way to run them, provided you have the regional sales history it needs.
Ghost ads solve the cost problem of placebo tests. Their authors built the method at Google and tested it on Google’s display network. Compared with PSA or intent-to-treat tests, they found advertisers can measure lift just as precisely while spending at least an order of magnitude less (Johnson, Lewis, and Nubbemeyer, 2016).
One caution on platform tests. A platform lift test measures that platform’s ads with that platform’s data. It can tell you what that platform did. It can’t tell you what the rest of your media did. For cross-channel questions, a geo test run outside any single platform gives the fuller answer.
How Do You Run an Incrementality Test?
To run an incrementality test, define one question, lock the success metric, choose a design, size the test, run it long enough to cover your buying cycle, hold everything else steady, and read the result as a range before you act. Here’s the sequence:
- Write down the question. One channel or tactic, one decision. Start from what your attribution shows, such as the channel carrying the most budget or the one growing fastest. “Did CTV lift sales in the regions where it ran?” is testable. “Is our marketing working?” isn’t.
- Pick the success metric before the test starts. Purchases, qualified leads, revenue, or new customers. Not clicks. Choosing the metric after the results come in is how tests get gamed.
- Choose the design. Platform lift for a single walled garden, geo-lift for cross-channel and offline questions, ghost ads where the platform offers them.
- Size the test. Estimate the smallest lift worth detecting and check that you have the volume to see it. Bigger holdouts add statistical power but cost more reach. Google allows holdouts up to 50% and notes the higher opportunity cost (Google).
- Set the duration. Cover at least one full buying cycle. The time-to-conversion data in your attribution reports shows how long that is. The next section covers the platform minimums.
- Freeze everything else. No new creative, budget swings, or promotions that hit one group and not the other. GeoLift’s guidance is to hold all other media constant across test and control markets (GeoLift Best Practices).
- Don’t stop early. Standard p-values and confidence intervals become unreliable when you keep checking a test and stop once it looks good (Johari, Pekelis, and Walsh, 2019). Decide the end date up front.
- Read the range, then act. Look at the confidence or credible interval before the headline lift. Use the result to calibrate that channel’s reporting and set its budget, then retest after big changes.
If you only remember one step, make it the second one. Pick the success metric before the test starts, not after you see the results.
How Long Should an Incrementality Test Run?
An incrementality test should run for at least two weeks and long enough to cover your typical buying cycle, plus a short window after the campaign ends for delayed conversions. Short tests undercount channels that work slowly. A test that’s too short can’t tell a slow channel from a weak one.
The platforms say the same. Google allows Conversion Lift studies as short as 7 days but typically recommends more than 14, and found up to a 17% drop in measured absolute lift in studies with a long conversion lag that ran for less than 14 days (Google). Some lift also lands after the ads stop. In Haus’s branded search tests, adding a post-treatment window raised measured direct-to-consumer lift by just under 10% on average, which Haus calls a fraction of the delayed lift seen for upper-funnel channels like YouTube (Haus, 2025). Meta’s GeoLift guidance sets a minimum of 15 days with daily data, or 4 to 6 weeks with weekly data (GeoLift Best Practices).
Your own sales cycle matters more than any platform default, and your attribution data is where to find it. Ashley Furniture’s Rex Debord has said that more than 40% of their customers take 90 days before they convert (read the case study). A two-week test for a brand like that would read only the fastest buyers. A test that ends before your buyers finish deciding will undercount every channel that works slowly.
How Do You Read Incrementality Test Results?
Read incrementality test results as a range, compare the incremental result with what attribution reported for the same channel and period, and use the ratio to calibrate that channel’s reporting until the next test. A close match confirms your reporting. A gap tells you which way to adjust.
- Check the interval first. A lift estimate whose range includes zero hasn’t proven anything yet. That isn’t the same as proving the ads don’t work. It usually means the test needed more volume or more time.
- Compare iROAS with reported ROAS. If the two are close, the test confirms your reporting. If they differ, the gap tells you how much to adjust that channel’s numbers, in either direction.
- Turn the gap into a factor. Divide incremental sales by platform-reported sales. A factor above 1 means the channel did more than its report showed, as with the $115 Meta drove for every $100 credited in Haus’s analysis (Haus, 2025). A factor below 1 means it did less. In Haus’s tests of Google brand-term ads, brands facing heavy competition on their own names saw a factor of 0.37, against 0.09 for brands facing little (Haus, 2025). Haus notes that branded search can still be profitable at a low factor, because the platform-reported return starts so high. The factor tells you how much to adjust. It doesn’t make the decision for you.
- Apply it and retest. Multiply that channel’s attributed results by the factor until the next test updates it. Factors drift as creative, competition, and spend change.
Then make the decision the test was built for. A channel that shows real lift has earned its budget, and often more. One that doesn’t deserves a closer look at its targeting, creative, and placements before you cut it, and your attribution data is where those answers are.
What Are the Most Common Incrementality Testing Mistakes?
The most common incrementality testing mistakes are tests that are too small or too short, control groups that leak, conclusions drawn from the wrong metric, and treating one test as the whole picture. Each one produces a confident answer to the wrong question.
- Testing too small. An underpowered test returns a range so wide it can’t separate a strong channel from a weak one.
- Ending too soon. Short tests miss delayed conversions. Google found up to a 17% drop in measured lift when long-lag studies ran under 14 days (Google).
- Leaky control groups. Holdout users who still see the campaign on another device, or neighboring markets that share media, shrink the measured lift.
- Measuring clicks instead of outcomes. A test can show strong lift on early actions and little on sales. Across 663 experiments at Facebook, median lift was 29% for upper-funnel outcomes and 5% for lower-funnel ones (Gordon, Moakler, and Zettelmeyer, 2023).
- Changing the campaign mid-test. New creative or a budget jump in one group breaks the comparison.
- Treating one test as permanent. Results age. Among regular testers, 47% run three to five tests a year (IAB, 2026), and a single test from last spring shouldn’t steer this year’s budget.
- Treating a test as a replacement for attribution. A test reads one channel over a few weeks. It can’t tell you which creative, audience, or placement drove the result, or what happened in the months between tests. Attribution covers both.
How Does Incrementality Testing Fit With Attribution and MMM?
Attribution is the foundation. It steers spend inside campaigns every day, incrementality tests give a controlled read on specific channels a few times a year, and media mix modeling sets channel budgets over quarters and years. Each answers a different question.
In the IAB’s words, incrementality measures causal lift, attribution captures conversion paths, and MMM informs budget allocation (IAB, 2026). Only 39% of US buy-side decision-makers use all three together (IAB, 2026).
- With attribution. Use each test result to confirm or calibrate marketing attribution for that channel, so daily decisions run on numbers that have been checked against a control group.
- With media mix modeling. Bayesian media mix models like Google’s Meridian can take lift-test results as priors, which calibrates the model with real-world results (Google, 2025).
- With the top line. Total revenue divided by total marketing spend, the marketing efficiency ratio, is the top-line check that sits above every channel’s reporting. Our take on MER vs ROAS explains why it belongs next to every lift test.
Genius Monkey is built attribution-first. Pixel Monkey attribution tracks the path to conversion across display, video, CTV, audio, and DOOH on one timeline, and it credits every channel that contributed instead of only the last one a buyer clicked. Our budget layer sits over 30+ DSPs and rebalances daily toward whatever is actually performing. Winners gain budget. Losers get cut. A lift test tells you how much one channel added over a few weeks. Pixel Monkey shows how every channel is contributing, every day.
The Bottom Line
Incrementality testing is how you prove what a channel added, measured against a group that never saw the ads. For nationwide and ecommerce brands with the volume to support it, it belongs in the plan a few times a year. It works best on top of attribution that sees the full path, which is where you’ll find the creative, audiences, and placements behind any lift a test turns up. Start with the channel that carries the biggest share of your budget.
If you want attribution that shows every channel’s contribution, from first impression to conversion, bring us a budget and a goal. We’ll show you the path to conversion. Request a demo to see how Genius Monkey measures every channel on one timeline.
Sources
- IAB and BWG Global. State of Data 2026: The AI-Powered Measurement Transformation. February 2026.
- TransUnion and EMARKETER. New TransUnion Research Reveals Marketers’ Confidence in Measurement Has Stalled. October 21, 2025.
- Google Ads Help. Strengthen media measurement and ROI clarity with incrementality testing improvements. November 11, 2025.
- Google Ads Help. Set up Conversion Lift based on users.
- Meta Business Help Center. About Confidence in Your Facebook Tests and Experiments.
- Meta Business Help Center. About lift and holdouts in Facebook advertising tests.
- Meta. GeoLift, open-source repository on GitHub.
- Meta. GeoLift Best Practices, GeoLift documentation.
- Haus. Is Meta Incremental? August 13, 2025.
- Haus. When Is Branded Search Worth the Investment? September 29, 2025.
- Blake, Nosko, and Tadelis. Consumer Heterogeneity and Paid Search Effectiveness: A Large-Scale Field Experiment. Econometrica, January 2015.
- Blake, Nosko, and Tadelis. Consumer Heterogeneity and Paid Search Effectiveness: A Large Scale Field Experiment. NBER Working Paper 20171, May 2014.
- Lewis and Rao. The Unfavorable Economics of Measuring the Returns to Advertising. The Quarterly Journal of Economics, 2015.
- Johnson, Lewis, and Nubbemeyer. Ghost Ads: Improving the Economics of Measuring Ad Effectiveness. Working paper, February 18, 2016.
- Johari, Pekelis, and Walsh. Always Valid Inference: Bringing Sequential Analysis to A/B Testing. arXiv, revised July 16, 2019.
- Gordon, Moakler, and Zettelmeyer. Close Enough? A Large-Scale Exploration of Non-Experimental Approaches to Advertising Measurement. Marketing Science, July 2023.
- Google. Meridian is now available to everyone. January 29, 2025.
- Genius Monkey. Ashley Furniture expanded their customer base and increased in-store conversions nationwide with Genius Monkey. Case study.
- Genius Monkey. Rethinking ROAS: Why Advertisers Should Pay More Attention to MER.
- Genius Monkey. About Genius Monkey.


